An application may report that its servers are operating normally while customers remain unable to complete transactions. Login verification codes fail to arrive. Payments receive no confirmation. Receipt emails are delayed. Or a delivery service never receives an order that has already been created.
From the business owner's perspective, the application is not working.
Technically, its core components may still be running. The failure could be occurring within an external service responsible for one part of the process.
Situations like these demonstrate why digital reliability cannot be assessed solely by whether a company's own servers remain online.
The more important question is: can customers still complete the tasks they came to perform?
One Transaction, Many Dependencies
Modern applications are rarely built as completely independent systems.
A sales application might use an identity provider for login, a cloud database for transactions, a payment gateway for checkout, an email service for receipts, object storage for files, and a notification provider for customer communication.
Each service has its own infrastructure, policies, capacity, and potential failure conditions.
In Key Practices in Cyber Supply Chain Risk Management, NIST explains that digital organisations increasingly depend on supplier ecosystems they cannot fully control or observe.
In July 2026, NIST also published SP 1326, a due diligence guide for information and communications technology suppliers. The assessment considerations include resilience and supply-chain tiers.
Although the NIST framework focuses on cybersecurity supply-chain risk, understanding suppliers and their dependencies is also relevant to operational-risk thinking.
A business may own one application, but that application can depend on numerous other organisations.
Uptime Does Not Fully Describe Customer Experience
A monitoring dashboard may show that the main API is responding successfully.
But is checkout working?
Are successful payments being recorded?
Are customers receiving confirmations?
Are orders reaching fulfilment?
If any of these steps fail, apparently healthy infrastructure may not reflect the actual customer experience.
The Google Cloud Well-Architected Framework defines reliability around a system's ability to perform its intended functions consistently. Its guidance also recommends defining reliability in relation to user-experience objectives rather than infrastructure status alone.
This changes what businesses should measure.
For e-commerce, checkout and payment completion may be critical. For a point-of-sale application, accurate order recording may matter more than immediate email delivery. For an insurance service, successfully saving a claim submission and its supporting documents may be the essential journey.
Monitoring should therefore follow business transactions, not only servers.
What Should Happen When a Vendor Fails?
Not every failure should have the same consequences.
If an email provider is unavailable, an application may still save the order and send the receipt when service returns.
If an AI recommendation service fails, customers may still be able to use ordinary search.
If a maps service becomes unavailable, users might be offered manual address entry, provided verification and fulfilment remain feasible.
A payment gateway failure, however, requires more caution. An application must not declare a payment successful simply because a customer pressed the payment button. Transaction status needs to follow trustworthy confirmation and proper reconciliation.
The relevant principle is graceful degradation: when some capabilities are disrupted, the system continues offering functions that remain safe and feasible, even with a reduced experience.
Google Cloud describes graceful degradation as an approach that preserves useful functionality under adverse conditions rather than allowing every disruption to become a complete failure.
A fallback does not mean forcing every transaction to continue. For processes involving money, identity, or sensitive information, temporarily suspending certain functions may be safer than proceeding without adequate controls.
Retrying Is Not Always the Solution
When an external service fails, retrying the request seems like a natural response.
Uncontrolled retries, however, can make the problem worse.
Amazon's Builders' Library explains the importance of timeouts, bounded retries, exponential backoff, and jitter in distributed systems. When many applications retry simultaneously, an overloaded service may experience another surge and struggle further to recover.
For business transactions, retries introduce another concern: duplication.
If a payment or order request was processed but its response was lost, resending it without suitable safeguards may create duplicate transactions.
Systems therefore need to consider idempotency, transaction states, and reconciliation rather than relying solely on a “try again” button.
Digital resilience combines technical architecture with accurate business rules.
Map Dependencies Around Customer Journeys
As an operational framework, GATICORP proposes:
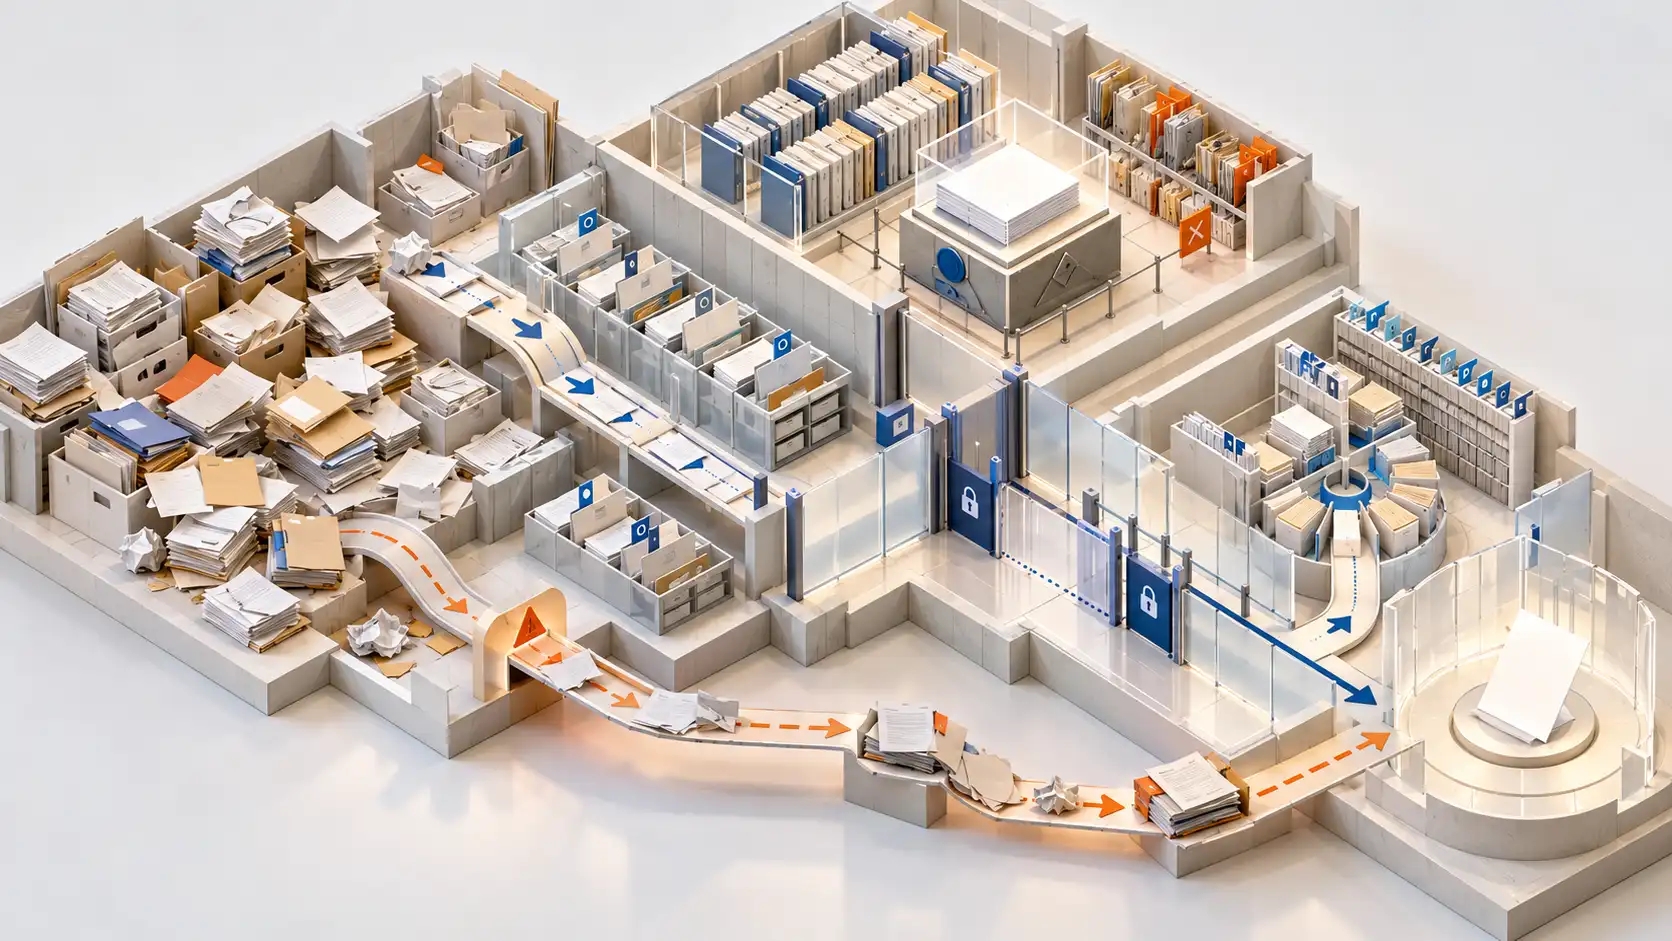
Critical Journey → Dependency → Failure Mode → Customer Impact → Fallback → Recovery
First, identify the activities most important to the business, such as accepting orders, processing payments, issuing policies, or recording point-of-sale transactions.
Second, map the external services needed to complete them. Go beyond vendor names to understand the specific functions involved and any relevant downstream dependencies.
Third, consider realistic failure modes: timeouts, regional disruptions, delayed webhooks, authentication errors, or temporary service unavailability.
Fourth, assess the effects on customers and operations.
Fifth, define safe fallback behaviour, including when a process may continue, must wait, or should stop.
Finally, establish recovery procedures and methods for reconciling delayed transactions.
This is not an official NIST or Google Cloud standard. It is a simplified way to translate dependency management into operational decisions that business teams can understand.
Resilience Must Be Tested
A disaster recovery document can look complete without actually working when needed.
Google Cloud recommends periodically testing recovery capabilities, including failover, rollback, and restoration from backups. The purpose is not merely to confirm that backup systems exist, but to demonstrate that recovery processes can be executed.
For smaller businesses, testing does not need to begin with a large-scale infrastructure simulation.
Teams can start with practical questions: what happens if the email provider stops responding for an hour? What if a payment webhook arrives late? What if notifications fail during a busy sales period?
Testing should examine not only whether the application returns to normal, but also whether transactions created during the disruption remain complete, non-duplicated, and traceable.
Digital Businesses Need Dependency Maps
Using cloud infrastructure and third-party services is not inherently a mistake. These technologies allow businesses to build products more quickly without operating every component themselves.
The efficiency, however, creates a different responsibility.
Organisations need to understand what they control, what depends on vendors, and which business processes are most exposed when a service becomes unavailable.
Service-level agreements can establish service expectations, but they do not automatically guarantee that every customer journey will succeed. A single transaction may depend on several providers with different commitments and operating conditions.
A vendor list alone is therefore insufficient.
Businesses need dependency maps connected to critical operations.
A reliable application is not one that promises never to experience an outage. No architecture can provide an absolute guarantee of that kind.
A more resilient application is designed to detect failures, contain their impact, preserve transaction integrity, and recover in a controlled manner.
When one service stops, the business does not always have to stop with it. But decisions about what may safely continue should be made before the disruption occurs.
- NIST IR 8276 — Key Practices in Cyber Supply Chain Risk Management, February 2021. Used for the concept of organisational dependence on suppliers and limited visibility or control across technology ecosystems.
- NIST SP 1326 — Cybersecurity Supply Chain Risk Management: Due Diligence Assessment Quick-Start Guide, 8 July 2026. Used for ICT supplier assessment, resilience, and supply-chain tiers.
- Google Cloud — Well-Architected Framework: Reliability Pillar. Used for reliability, resilience, monitoring, and user-experience-oriented objectives.
- Google Cloud — Design for Graceful Degradation. Used for the principle of preserving feasible functionality when systems face disruption or constrained operating conditions.
- Amazon Builders' Library — Timeouts, Retries, and Backoff with Jitter. Used for the risks of excessive retries and the roles of timeouts, backoff, and jitter in distributed systems.
- Google Cloud — Perform Testing for Recovery from Failures. Used for the importance of failover, rollback, and data-restoration testing.
- Editorial notes: This article intentionally does not rely on a particular vendor incident because an individual outage is not necessary to establish the structural risk. Checkout, email, payment gateway, AI API, and notification examples are illustrative scenarios, not reports of specific incidents. Critical Journey → Dependency → Failure Mode → Customer Impact → Fallback → Recovery is a GATICORP editorial framework, not an official NIST or Google Cloud methodology.
Published: October 15, 2026